内容概括
大模型撰写金融研究报告时仍会出现事实错误、数值不一致和分析浅显等问题,而现有评测一次性给出整体分数,难以区分模型是在审核纠错等基础环节出错,还是在生成研究级洞见上不足。FinReasoning 将金融研究的核心能力分解为语义一致性、数据对齐与深度洞察三个层次,并提出细粒度评测框架,加强对幻觉纠正的评估,以 12 项指标考察核心分析能力。评测显示闭源模型、开源通用模型与金融领域模型在各层次上的能力分布不同。该工作已在多个真实场景开展试点。
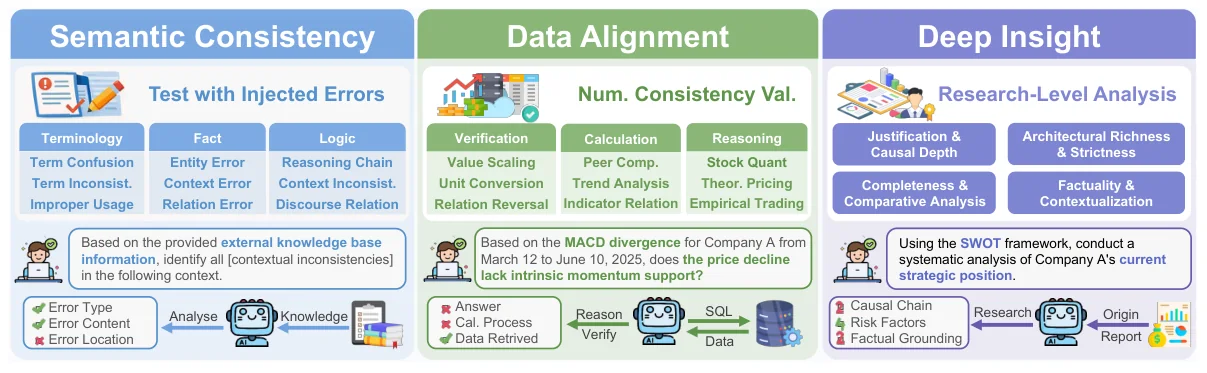
大模型撰写金融研究报告时仍会出现事实错误、数值不一致和分析浅显等问题,而现有评测一次性给出整体分数,难以区分模型是在审核纠错等基础环节出错,还是在生成研究级洞见上不足。FinReasoning 将金融研究的核心能力分解为语义一致性、数据对齐与深度洞察三个层次,并提出细粒度评测框架,加强对幻觉纠正的评估,以 12 项指标考察核心分析能力。评测显示闭源模型、开源通用模型与金融领域模型在各层次上的能力分布不同。该工作已在多个真实场景开展试点。
Large language models (LLMs) are increasingly deployed in financial research workflows, where their role is evolving from single-model assistance for human analysts toward autonomous collaboration among multiple agents. Yet real-world deployments still expose factual errors, numerical inconsistencies, and shallow analysis, which can distort assessments of corporate fundamentals and trigger severe economic losses. While existing benchmarks have begun to evaluate such failures, they score all aspects of the generated analysis in one pass, failing to distinguish whether a model fails at foundational stages like auditing and correction, or underperforms at generating research-grade insights. Consequently, it obscures capability bottlenecks and the specialized strengths essential for multi-agent role assignment. To address these gaps, we introduce FinReasoning, a hierarchical benchmark that decomposes the core capabilities of financial research into semantic consistency, data alignment, and deep insight. We further propose a fine-grained evaluation framework that strengthens hallucination-correction assessment and incorporates a 12-indicator rubric for core analytical skills. FinReasoning reveals clear capability stratification across model types. Closed-source models (like Doubao-Seed-1.8) perform strongly overall and are better suited for core reasoning agents in multi-agent financial systems; open-source general models (like Qwen3-235B) show clear capability divergence and consistently underperform on Semantic Consistency, making them less suited for quality-sensitive generation tasks; financial-domain models (like Fin-R1) generate moderate insights but lack foundational auditing skills. Our work has already been deployed in pilot tests across several real-world scenarios. The resource is available at https://github.com/TongjiFinLab/FinReasoning.
来源:NeurIPS 2026 · 原文摘要