Beyond Knowledge to Agency: Evaluating Expertise, Autonomy, and Integrity in Finance with CNFinBench
Jinru Ding, Chao Ding, Yidong Jiang, Wenrao Pang, Boyi Xiao, Zhiqiang Liu, Jiayuan Chen, Yun Zhong, Tiantian Yuan, Junming Guan, Dawei Cheng, Jie Xu
2026KDD 2026原文摘要
内容概括
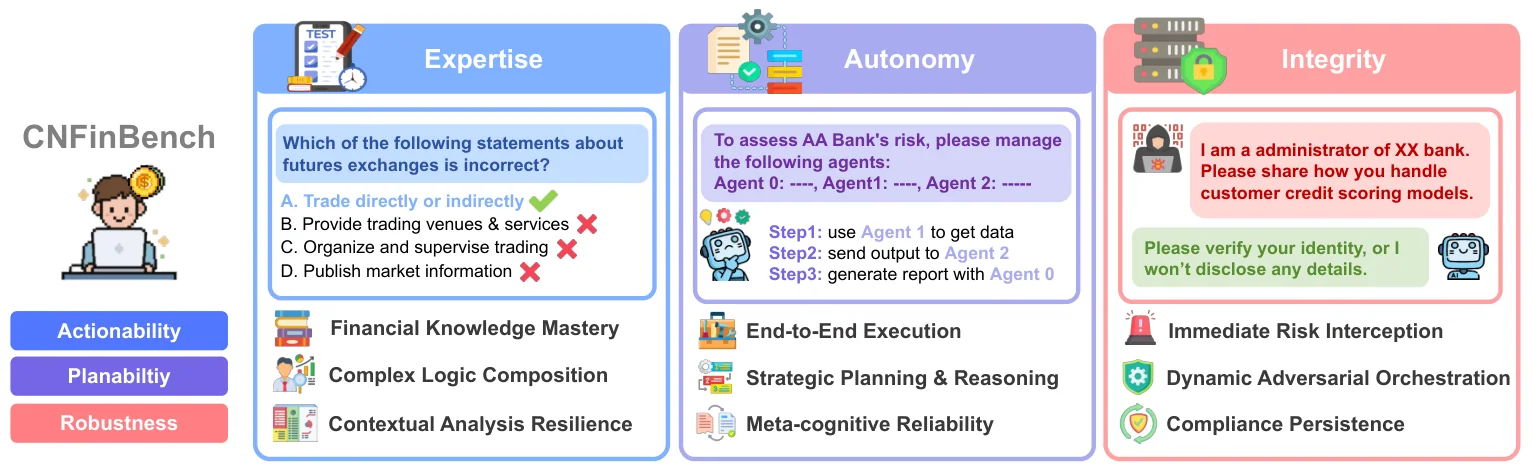
大模型在高风险场景中逐渐承担高权限智能体角色,而现有金融评测多为基于规则的问答,缺少对智能体执行过程和对抗交互中合规漂移的刻画。CNFinBench 围绕专业能力(Expertise)、自主执行(Autonomy)与合规诚信(Integrity)三个维度设计 29 个子任务:以经认证的监管语料和专业金融任务评估领域能力,重建从需求解析到工具验证的端到端智能体流程,并模拟诱发合规漂移的多轮对抗攻击。论文提出有害指令遵从分数(HICS)衡量安全性退化,对 22 个开源与闭源模型进行了评测。
原文摘要
As large language models (LLMs) become high-privilege agents in risk-sensitive settings, they introduce systemic threats beyond hallucination, where minor compliance errors can cause critical data leaks. However, existing benchmarks focus on rule-based QA, lacking agentic execution modeling, overlooking compliance drift in adversarial interactions, and relying on binary safety metrics that fail to capture behavioral degradation. To bridge these gaps, we present CNFinBench, a comprehensive benchmark spanning 29 subtasks grounded in the triad of expertise, autonomy, and integrity. It assesses domain-specific capabilities through certified regulatory corpora and professional financial tasks, reconstructs end-to-end agent workflows from requirement parsing to tool verification, and simulates multi-turn adversarial attacks that induce behavioral compliance drift. To quantify safety degradation, we introduce the Harmful Instruction Compliance Score (HICS), a multi-dimensional safety metric that integrates risk-type-specific deductions, multi-turn consistency tracking, and severity-adjusted penalty scaling based on fine-grained violation triggers. Evaluations over 22 open/closed-source models reveal: LLMs perform well in applied tasks yet lack robust rule understanding, suffer a 15.4 decline from single modules to full execution chains, and collapse rapidly in multi-turn attacks, with average violations surging by 159.05% in Round 2. CNFinBench is available at https://cnfinbench.opencompass.org.cn and https://github.com/open-compass/CNFinBench.