内容概括
现有基于深度强化学习的交易方法要么只做低频的投资组合优化,要么只支持少量资产和离散动作空间,计算效率面临挑战。DRPO 用马尔可夫决策过程建模组合管理任务,在动作空间中直接推断股票权重;将环境拆分为“静态”的市场状态与“动态”的持仓权重状态以降低交互复杂度,并通过概率动态规划设计高效的奖励期望计算算法,使智能体无需依赖轨迹采样即可获得反馈。实验使用道琼斯、Coinbase 与上交所的真实数据。
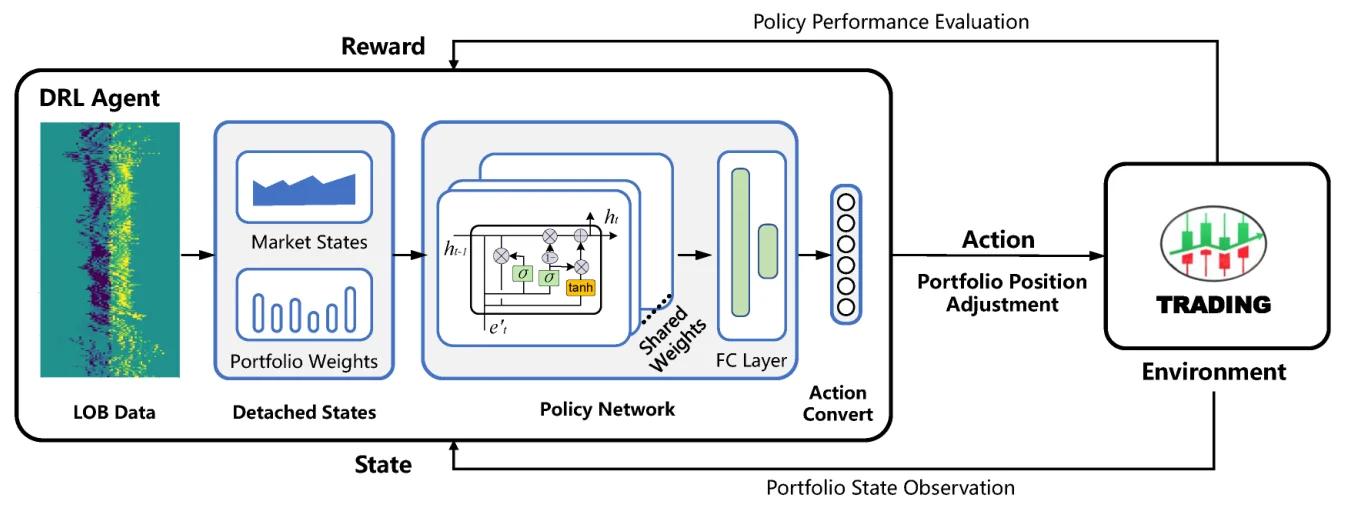
现有基于深度强化学习的交易方法要么只做低频的投资组合优化,要么只支持少量资产和离散动作空间,计算效率面临挑战。DRPO 用马尔可夫决策过程建模组合管理任务,在动作空间中直接推断股票权重;将环境拆分为“静态”的市场状态与“动态”的持仓权重状态以降低交互复杂度,并通过概率动态规划设计高效的奖励期望计算算法,使智能体无需依赖轨迹采样即可获得反馈。实验使用道琼斯、Coinbase 与上交所的真实数据。
High-frequency trading is an extraordinarily intricate financial task, which is normally treated as a near real-time sequential decision problem. Compared with the traditional two-phase approach, forecasting equity’s trend and then weighting them by combinatorial optimization, deep reinforcement learning (DRL) methods have shown advances in reward chasing with optimal policies. However, existing DRL-based methods either leverage portfolio optimization on low-frequency scenarios or only support a very limited number of assets with discrete action space, facing significant computing efficiency challenges. Therefore, we propose an efficient DRL-based policy optimization (DRPO) method for high-frequency trading. In particular, we model the portfolio management task with Markov Decision Process by directly inferring the equity weights in the action space guided by maximum accumulated returns. To reduce agents’ interaction complexity without reducing interpretation, we detach the environment into the “static” market states and “dynamic” portfolio weight states. Then, we design an efficient reward expectation calculation algorithm via probabilistic dynamic programming, which enables our agents directly collect feedback away from trajectory sampling-based morass. To the best of our knowledge, this is the first work that solves the high-frequency portfolio optimization problem by devising an efficient continuous space policy optimization algorithm in the DRL framework. Through extensive experiments on the real-world data from Dow Jones, Coinbase and SSE exchanges, we show that our proposed DRPO significantly outperforms state-of-the-art benchmark methods. The results demonstrate the practical applicability and effectiveness of the proposed method.
来源:KDD 2023 · 原文摘要