内容概括
医疗保险欺诈模式不断演化,基于历史数据离线训练的模型难以识别新出现的欺诈模式,而现有增量学习模型主要针对灾难性遗忘设计。POCL 结合对比学习预训练与在线更新:预训练阶段在历史数据上用对比学习获得风险表示;在线学习阶段采用时序记忆感知突触(Temporal Memory Aware Synapses)更新策略,基于持续出现的新数据做增量优化,在适应新欺诈模式的同时减少对既有知识的遗忘。实验在真实保险欺诈数据集上进行,并比较了运行时间与空间开销。
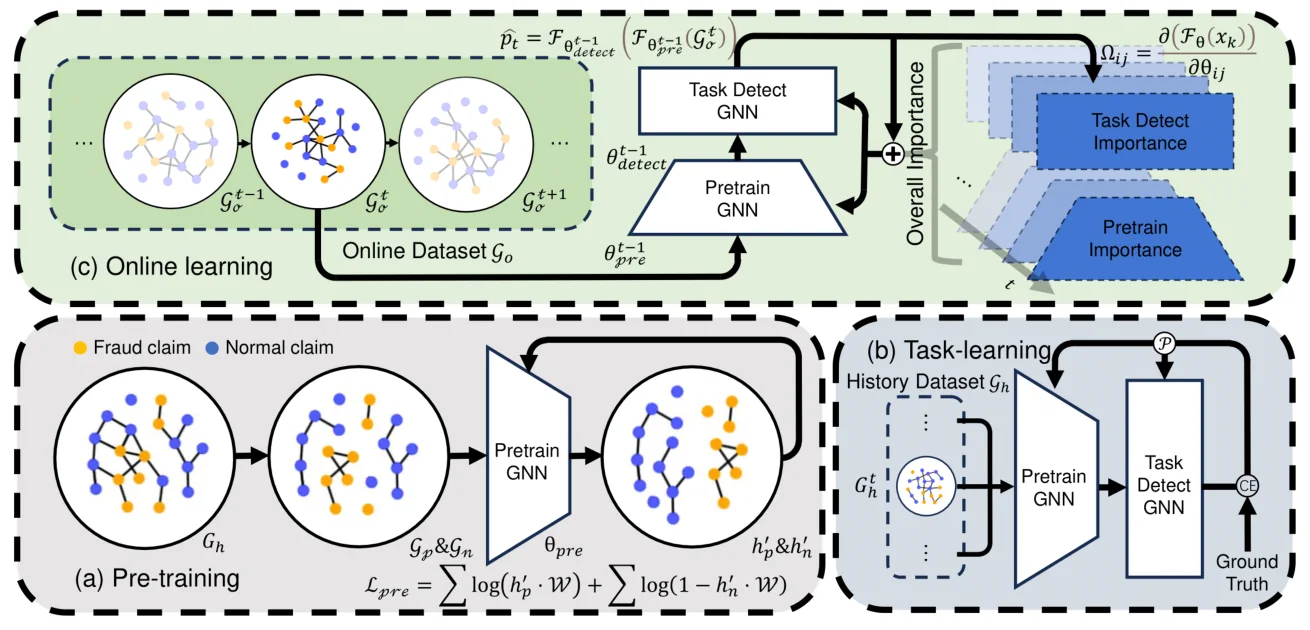
医疗保险欺诈模式不断演化,基于历史数据离线训练的模型难以识别新出现的欺诈模式,而现有增量学习模型主要针对灾难性遗忘设计。POCL 结合对比学习预训练与在线更新:预训练阶段在历史数据上用对比学习获得风险表示;在线学习阶段采用时序记忆感知突触(Temporal Memory Aware Synapses)更新策略,基于持续出现的新数据做增量优化,在适应新欺诈模式的同时减少对既有知识的遗忘。实验在真实保险欺诈数据集上进行,并比较了运行时间与空间开销。
Medical insurance fraud has always been a crucial challenge in the field of healthcare industry. Existing fraud detection models mostly focus on offline learning scenes. However, fraud patterns are constantly evolving, making it difficult for models trained on past data to detect newly emerging fraud patterns, posing a severe challenge in medical fraud detection. Moreover, current incremental learning models are mostly designed to address catastrophic forgetting, but often exhibit suboptimal performance in fraud detection. To address this challenge, this paper proposes an innovative online learning method for medical insurance fraud detection, named POCL. This method combines contrastive learning pre-training with online updating strategies. In the pre-training stage, we leverage contrastive learning pre-training to learn on historical data, enabling deep feature learning and obtaining rich risk representations. In the online learning stage, we adopt a Temporal Memory Aware Synapses online updating strategy, allowing the model to perform incremental learning and optimization based on continuously emerging new data. This ensures timely adaptation to fraud patterns and reduces forgetting of past knowledge. Our model undergoes extensive experiments and evaluations on real-world insurance fraud datasets. The results demonstrate our model has significant advantages in accuracy compared to the state-of-the-art baseline methods, while also exhibiting lower running time and space consumption. Our sources are released at https://github.com/finint/POCL.
来源:AAAI 2024 · 原文摘要